1Tsinghua IIIS2The Chinese University of Hong Kong3Renmin University of China4Tsinghua College AI5Tsinghua Weiyang College
HuMiT uses a compact reference target to drive responsive whole-body teleoperation, with approximately 20 ms communication-to-inference latency and 65 ms median operator-to-robot latency measured from video.
Real-time whole-body humanoid teleoperation remains challenging due to the computational latency introduced by optimization-based retargeting pipelines and future-frame conditioning. Existing motion tracking policies typically require dense reference targets including full joint positions, body-part transformations, and even future frames, which tightly couples the controller to expensive upstream modules.
In this work, we present HuMiT, a whole-body teleoperation system built on a unified tracking policy that requires only a compact reference target, consisting of root height, root velocity, and the SE(3) poses of four sparse keypoints at the current frame, yet achieves competitive tracking fidelity compared to methods relying on more diverse reference states including complete joint positions, dense body-part transformations, and even future frames.
Experiments show that our policy achieves a communication-to-inference latency of ∼20 ms measured between headset streaming and policy output and a video-based optical flow latency of 65 ms (median) across different motion types.
We validate the system on a Unitree G1 humanoid, showcasing split-second reactive responses such as catching a tossed ball, as well as coordinated loco-manipulation capabilities. Project page: https://xiaohu-art.github.io/Track/.
Method
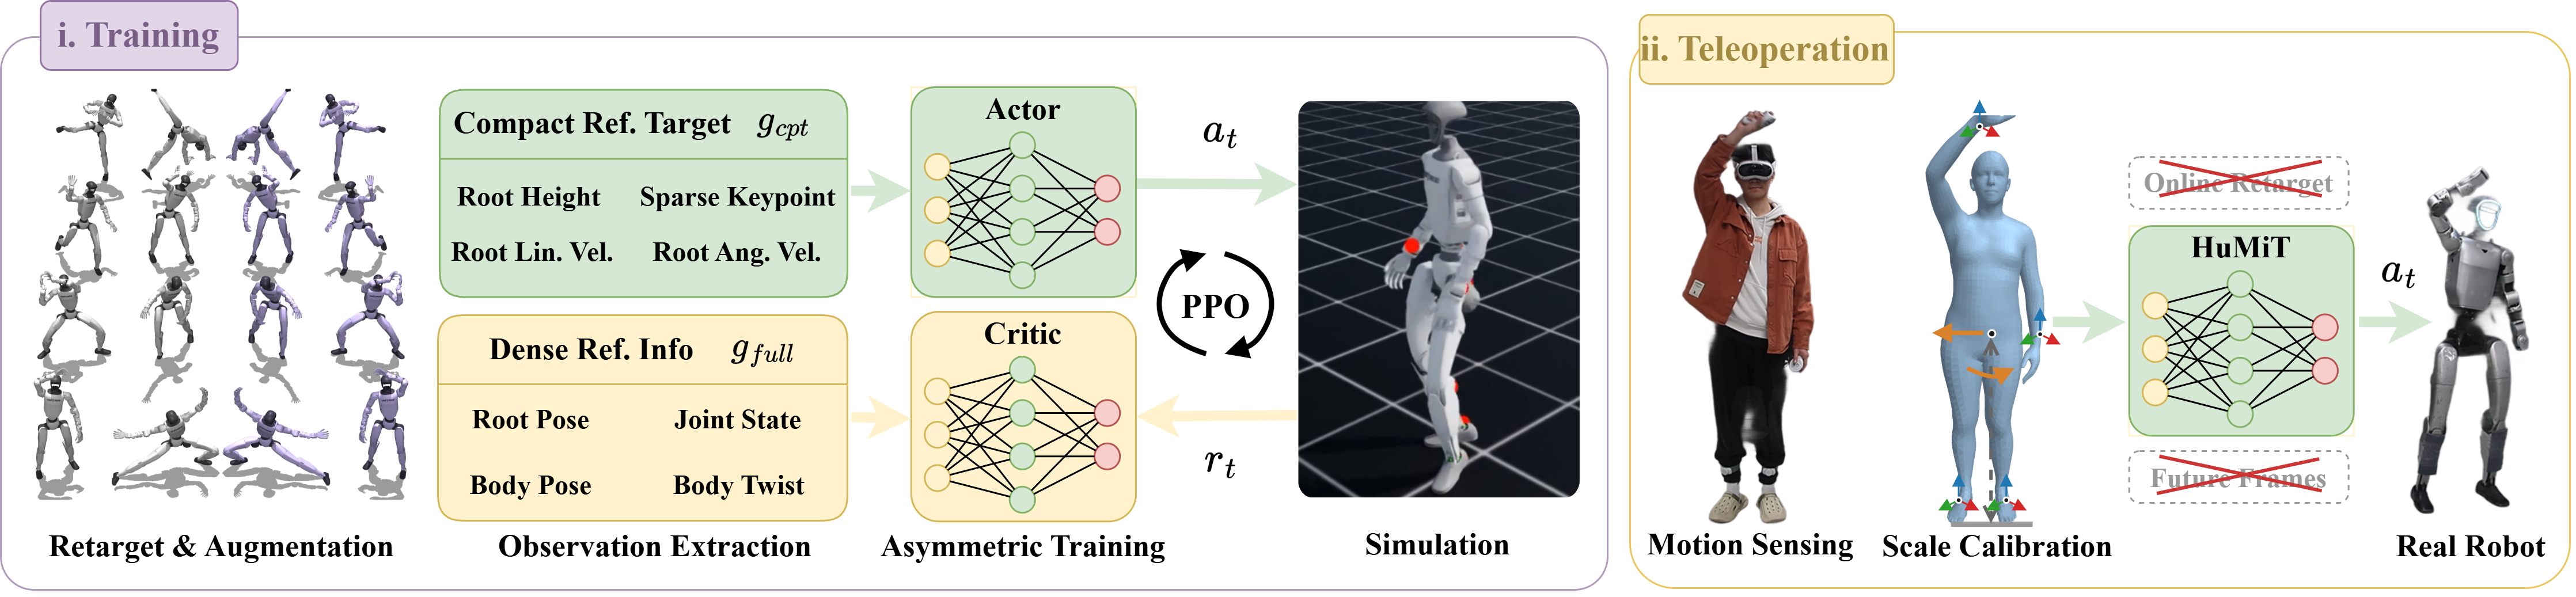
The central design choice of HuMiT is that π observes only the compact reference target (CRT) —root height, root linear and angular velocity, and the root-relative SE(3) poses of four sparse keypoints (both wrists and ankles) at the current frame—without joint-level references, states of the remaining body parts, or future-frame information. This reduces the upstream pipeline to two lightweight components:
A motion-sensing module that captures the operator's body keypoints via a VR headset with motion trackers,
A scale-calibration module that maps human keypoint positions to the robot's body positions in closed form, in place of an optimization-based retargeting loop.
Method overview. Human motion passes through scale calibration to produce a compact reference target. Online inverse kinematics and future-frame buffering are removed. During training, the Actor receives the compact reference and proprioception, while the Critic also observes privileged states and full retargeted references.
Latency Measurement
To measure end-to-end latency, we record the operator and robot in the same camera frame at 200 fps during punching, squatting, and waving, then match peaks of their optical-flow motion signals.
HuMiT achieves approximately 20 ms communication-to-inference latency and 65 ms median end-to-end latency across the three motion types. Under the same external protocol, the paper reports 245 ms for SONIC, 145 ms for SONIC-LL, and 120 ms for TWIST2.
Side-by-side recording of the operator and the Unitree G1 used for the latency analysis.
Teleoperation Tracking
Beyond raw latency, the policy must faithfully reproduce the operator's intent in real time. We qualitatively evaluate whole-body tracking by streaming live human motion to the Unitree G1 and observing how closely the robot mirrors arm gestures, locomotion, and coupled upper–lower-body coordination.
Real-time teleoperation tracking on the Unitree G1: the robot follows the operator's whole-body motion driven by the compact reference target alone.
Reactive Response
Low end-to-end latency unlocks tasks that demand split-second reactions. We toss a ball toward the operator: the operator reaches out instinctively, and the robot mirrors the motion in real time, catching the ball with its glove. Even moderate teleoperation delays would make this task infeasible.
Coordinated Whole-Body Skills
Driven by a single unified policy, the operator commands the Unitree G1 through a range of everyday whole-body skills: carrying a water jug, pushing a chair, walking up to and sitting on a chair, and reaching overhead to hang clothes. These behaviors require tight coordination between locomotion and manipulation, which decoupled upper–lower-body controllers struggle to achieve.
Carrying a water jug across the workspace.Pushing a chair while walking.Walking up to a chair and sitting down.Reaching overhead to hang clothes.
Failure Cases
While HuMiT supports a wide range of whole-body skills, certain behaviors remain challenging. We highlight two representative failure modes below.
Kneeling failed. Kneeling fails due to insufficient training trajectories covering ground-contact motions.Placing failed. Precise placement occasionally fails due to scale mismatch between the human and the robot, reducing fine-grained wrist accuracy.